Databricks notebooks help data engineers and analysts build reusable data processing workflows with Python, Scala, SQL, and R. In many projects, one notebook needs to call another notebook to reuse code, pass parameters, or orchestrate a sequence of tasks.
This guide explains how to run a Databricks notebook from another notebook using %run and dbutils.notebook.run(). It also covers parameter passing, return values, sequential execution, and running notebooks in parallel.
Prerequisites:
1. An Azure Databricks, Databricks on AWS, or Databricks on Google Cloud workspace.
2. Access to a compute resource that can run the notebooks.
3. Permission to view and run the target notebook.
4. Basic knowledge of creating and running Databricks notebooks.
Two Ways to Run a Databricks Notebook from Another Notebook
Databricks provides two commonly used notebook-to-notebook execution methods:
%run: Executes another notebook in the current notebook context and makes its variables and functions available to the caller.dbutils.notebook.run(): Runs another notebook as a separate notebook job, supports string parameters, and returns a string result.
1. Run a Notebook Using %run
Use %run when you want to reuse functions, variables, configuration values, or helper code from another notebook. The called notebook runs in the same notebook context as the calling notebook.
%run /Shared/common_functions
You can also pass widget values to the notebook:
%run /Shared/common_functions $environment="dev"

When should you use %run?
- To load shared functions or reusable helper code.
- To load common configuration variables.
- To reuse notebook code without creating a separate orchestration job.
Important: Because %run uses the same notebook context, variables and functions defined in the called notebook become available to the calling notebook. It is therefore useful for code modularization, but it can also create tight coupling between notebooks.
2. Run a Notebook Using dbutils.notebook.run()
Use dbutils.notebook.run() when you want to execute another notebook as a separate run, pass parameters, and receive a return value.
dbutils.notebook.run(notebook_path, timeout_seconds, arguments)
The arguments are:
- notebook_path: The workspace path or relative path of the target notebook.
- timeout_seconds: Maximum time allowed for the run. Use
0for no timeout. - arguments: A map of string key-value pairs used to set widgets in the target notebook.
Example:
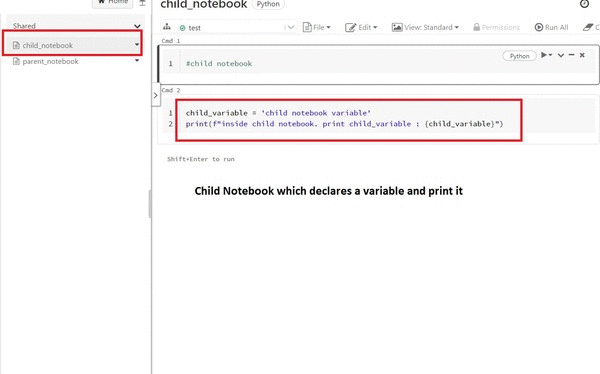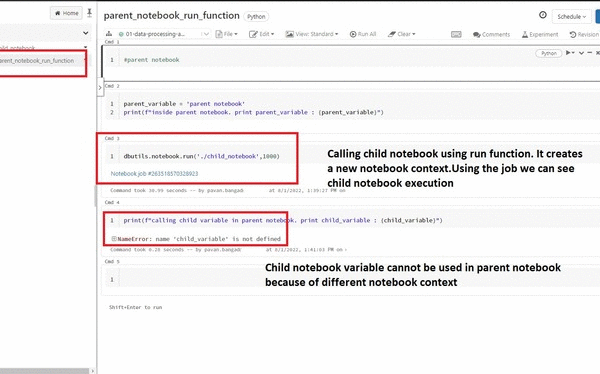
result = dbutils.notebook.run(
    "/Shared/child_notebook",
    60,
    {"environment": "dev", "load_date": "2026-09-17"}
)

print(result)
Create widgets in the child notebook
The target notebook can read the values passed by the parent notebook through widgets:
dbutils.widgets.text("environment", "dev")
dbutils.widgets.text("load_date", "")

environment = dbutils.widgets.get("environment")
load_date = dbutils.widgets.get("load_date")

print(f"Environment: {environment}")
print(f"Load date: {load_date}")
Return a value from the child notebook
Use dbutils.notebook.exit() in the child notebook to return a string to the calling notebook:
dbutils.notebook.exit("Notebook completed successfully")
The parent notebook receives the value returned by dbutils.notebook.run(). If you need to return multiple values, serialize them as JSON or write the result to a table or storage location and return its identifier.
Run Multiple Databricks Notebooks Sequentially
You can call multiple notebooks one after another from a parent notebook. The next call starts after the previous call finishes.

dbutils.notebook.run("/Shared/notebook_1", 0)
dbutils.notebook.run("/Shared/notebook_2", 0)
dbutils.notebook.run("/Shared/notebook_3", 0)
This pattern is useful when notebook 2 depends on the successful completion of notebook 1. For production workflows with dependencies, schedules, retries, and monitoring, consider using Databricks Jobs/Lakeflow Jobs instead of building the entire orchestration flow inside a notebook.
Run Databricks Notebooks in Parallel
If several notebooks are independent, you can start them concurrently using Python’s concurrent.futures library.
from concurrent.futures import ThreadPoolExecutor

notebooks = [
    "/Shared/notebook_1",
    "/Shared/notebook_2",
    "/Shared/notebook_3"
]

def run_notebook(path):
    return dbutils.notebook.run(path, 0)

with ThreadPoolExecutor(max_workers=3) as executor:
    results = list(executor.map(run_notebook, notebooks))

print(results)
Use parallel execution only when the notebooks do not depend on one another and the available compute resources can handle the additional workload. For managed production orchestration, Databricks Jobs/Lakeflow Jobs or Azure Data Factory may be a better fit.
You can read more about Python ThreadPoolExecutor.
Download the sample notebook used in this article:
Important Notes and Limitations
%runis intended mainly for code reuse and modularization. It does not provide the same parameter and return-value behavior asdbutils.notebook.run().dbutils.notebook.run()accepts string arguments and returns a string. Serialize structured values such as JSON when required.- The called notebook must be accessible to the user or identity running the parent notebook.
- Set an appropriate timeout and handle failures when calling notebooks from production workflows.
- Databricks Jobs created through the notebook API have a maximum run duration of 30 days.
- For complex dependencies, scheduling, retries, alerts, and observability, use Databricks Jobs/Lakeflow Jobs or an orchestration service such as Azure Data Factory.
Summary
Use %run when you need to reuse code from another notebook in the same context. Use dbutils.notebook.run() when you need to execute a notebook separately, pass parameters, and receive a result. For larger production pipelines, use a managed orchestration tool with dependency management, retries, scheduling, and monitoring.
See more

Visual Studio Marketplace
SSIS Catalog Migration Wizard
Extend Visual Studio with an easy way to migrate SSIS Catalog projects.

Pavan Bangad
9+ years of experience in building data warehouse and big data application.
Helping customers in their digital transformation journey in cloud.
Passionate about data engineering.